
- Eight-LPU server system and live remote demonstration of LLM inference running on operational servers in Korea
- Internal benchmarks show more than 3.5x higher token throughput per watt and per dollar compared with systems powered by NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs
- Event: SC26 (Supercomputing 2026)
- Date: November 17–19, 2026
- Venue: McCormick Place, Chicago, Illinois, USA
- HyperAccel Booth: #1411, AI Semiconductor Korea Pavilion
- Exhibition: Eight-LPU server system showcase and live remote LLM inference demonstration using operational servers in Korea
- Presentation by Joonyeon Kim: November 18, 2:30–2:45 p.m. CT
- Presentation Venue: Lablup Inc., Booth #4630
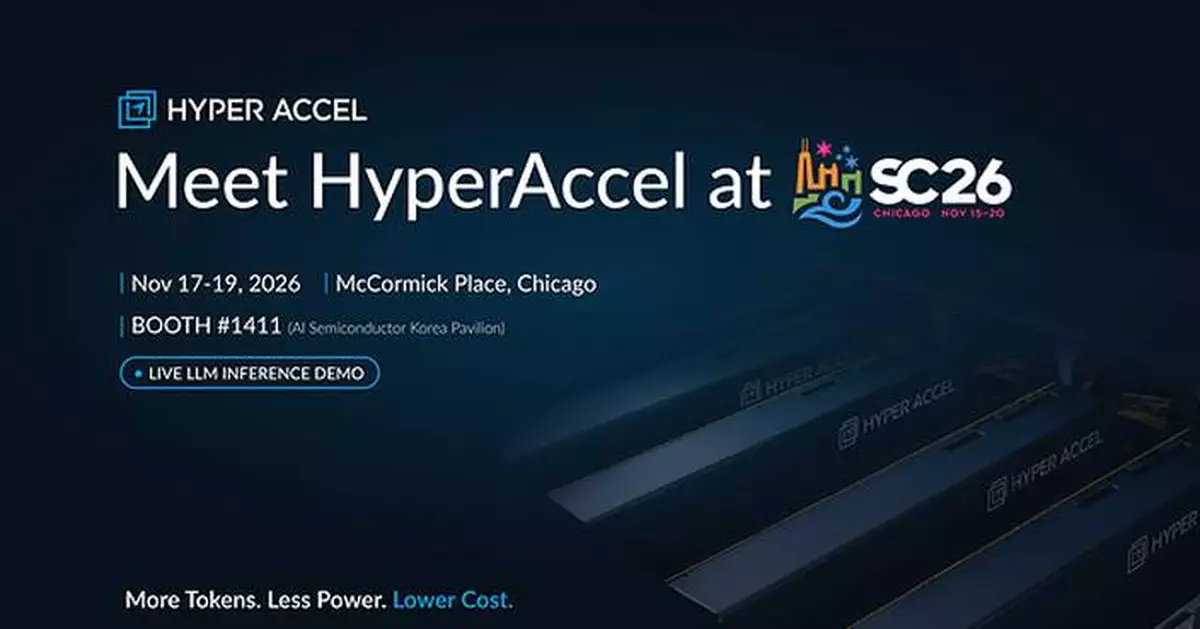
CHICAGO, Nov. 12, 2026 /PRNewswire/ -- HyperAccel, a South Korean fabless AI semiconductor company specializing in high-efficiency large language model (LLM) inference, will showcase its LPU (LLM Processing Unit) technology at SC26 (Supercomputing 2026), taking place November 17–19 at McCormick Place in Chicago. The company will present an eight-LPU server system and conduct a live remote demonstration of LLM inference running on operational servers deployed in Korea.
At the exhibition, HyperAccel will showcase how its LPU technology operates as part of a server-level system, extending beyond individual semiconductor components to practical AI infrastructure. Through a live remote demonstration from its server environment in Korea, visitors will be able to see LLM inference running on operational hardware and gain insight into the technology's potential for deployment in enterprise and data center environments.
According to HyperAccel's internal benchmarks, a server equipped with HyperAccel LPU cards (250W per card) delivers more than 3.5x higher token throughput per watt and per dollar than a comparable system powered by NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs (600W per card) when running Qwen3-32B and Llama3-70B models. With support for even larger LLMs, including Kimi and GLM models, HyperAccel's LPU demonstrates the potential to significantly improve the energy efficiency and economics of LLM inference, offering a compelling solution for enterprise AI infrastructure and data centers.
These efficiency gains stem from the HyperAccel LPU architecture, designed specifically for LLM inference. It pairs power-efficient LPDDR5X memory with HyperAccel's Streamlined Dataflow architecture, which achieves approximately 90% memory bandwidth utilization, compared with 50 to 60% for GPUs, reducing power consumption and operating costs in large-scale inference environments.
In addition to its main exhibition, Joonyeon Kim, CFO of HyperAccel, will deliver a presentation titled "Redefining AI Infrastructure Through Token Efficiency" at Lablup Inc.'s booth (#4630) on November 18, from 2:30 p.m. to 2:45 p.m. Central Time.
Through its participation in SC26, HyperAccel aims to expand its global presence and accelerate the adoption of LPU-based inference infrastructure. The company is seeking partnerships with global server manufacturers, cloud service providers, and AI infrastructure solution providers, focusing on server platform integration, technical validation, and business development opportunities in global data center markets.
"As AI adoption accelerates, the industry is shifting its focus from raw processor performance to the efficiency and economics of AI inference at scale," said Joo-Young Kim, CEO of HyperAccel. "At SC26, we are excited to showcase how our purpose-built LPU architecture delivers superior token efficiency at the server level, reducing the cost and power consumption of AI inference. We also look forward to engaging with global infrastructure partners to bring more efficient and scalable AI solutions to market."
Visitors can meet the HyperAccel team at the AI Semiconductor Korea Pavilion (Booth #1411) to learn more about its LPU technology, explore the eight-LPU server system, and watch the live remote LLM inference demonstration.
Event Information
About HyperAccel
HyperAccel is a South Korean fabless AI semiconductor company founded in 2023. The company develops LPUs (LLM Processing Units), AI accelerators purpose-built for large language model inference. Its proprietary architecture leverages power-efficient LPDDR5X memory and Streamlined Dataflow technology to improve energy efficiency and cost competitiveness in AI inference.
Its product portfolio includes Bertha, an AI accelerator for data center and enterprise applications, and Bertha-Edge, designed for on-device AI. HyperAccel is also expanding its technology into edge computing and physical AI applications.
The company received the IEEE Micro Best Paper Award in 2025 and was named to the Forbes Asia 100 To Watch 2026 list, among other industry recognitions. Headquartered in Seoul, South Korea, with a presence in Silicon Valley, HyperAccel is pursuing expansion in global AI semiconductor markets. Learn more at www.hyperaccel.ai.
CHICAGO, Nov. 12, 2026 /PRNewswire/ -- HyperAccel, a South Korean fabless AI semiconductor company specializing in high-efficiency large language model (LLM) inference, will showcase its LPU (LLM Processing Unit) technology at SC26 (Supercomputing 2026), taking place November 17–19 at McCormick Place in Chicago. The company will present an eight-LPU server system and conduct a live remote demonstration of LLM inference running on operational servers deployed in Korea.
At the exhibition, HyperAccel will showcase how its LPU technology operates as part of a server-level system, extending beyond individual semiconductor components to practical AI infrastructure. Through a live remote demonstration from its server environment in Korea, visitors will be able to see LLM inference running on operational hardware and gain insight into the technology's potential for deployment in enterprise and data center environments.
According to HyperAccel's internal benchmarks, a server equipped with HyperAccel LPU cards (250W per card) delivers more than 3.5x higher token throughput per watt and per dollar than a comparable system powered by NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs (600W per card) when running Qwen3-32B and Llama3-70B models. With support for even larger LLMs, including Kimi and GLM models, HyperAccel's LPU demonstrates the potential to significantly improve the energy efficiency and economics of LLM inference, offering a compelling solution for enterprise AI infrastructure and data centers.
These efficiency gains stem from the HyperAccel LPU architecture, designed specifically for LLM inference. It pairs power-efficient LPDDR5X memory with HyperAccel's Streamlined Dataflow architecture, which achieves approximately 90% memory bandwidth utilization, compared with 50 to 60% for GPUs, reducing power consumption and operating costs in large-scale inference environments.
In addition to its main exhibition, Joonyeon Kim, CFO of HyperAccel, will deliver a presentation titled "Redefining AI Infrastructure Through Token Efficiency" at Lablup Inc.'s booth (#4630) on November 18, from 2:30 p.m. to 2:45 p.m. Central Time.
Through its participation in SC26, HyperAccel aims to expand its global presence and accelerate the adoption of LPU-based inference infrastructure. The company is seeking partnerships with global server manufacturers, cloud service providers, and AI infrastructure solution providers, focusing on server platform integration, technical validation, and business development opportunities in global data center markets.
"As AI adoption accelerates, the industry is shifting its focus from raw processor performance to the efficiency and economics of AI inference at scale," said Joo-Young Kim, CEO of HyperAccel. "At SC26, we are excited to showcase how our purpose-built LPU architecture delivers superior token efficiency at the server level, reducing the cost and power consumption of AI inference. We also look forward to engaging with global infrastructure partners to bring more efficient and scalable AI solutions to market."
Visitors can meet the HyperAccel team at the AI Semiconductor Korea Pavilion (Booth #1411) to learn more about its LPU technology, explore the eight-LPU server system, and watch the live remote LLM inference demonstration.
Event Information
- Event: SC26 (Supercomputing 2026)
- Date: November 17–19, 2026
- Venue: McCormick Place, Chicago, Illinois, USA
- HyperAccel Booth: #1411, AI Semiconductor Korea Pavilion
- Exhibition: Eight-LPU server system showcase and live remote LLM inference demonstration using operational servers in Korea
- Presentation by Joonyeon Kim: November 18, 2:30–2:45 p.m. CT
- Presentation Venue: Lablup Inc., Booth #4630
About HyperAccel
HyperAccel is a South Korean fabless AI semiconductor company founded in 2023. The company develops LPUs (LLM Processing Units), AI accelerators purpose-built for large language model inference. Its proprietary architecture leverages power-efficient LPDDR5X memory and Streamlined Dataflow technology to improve energy efficiency and cost competitiveness in AI inference.
Its product portfolio includes Bertha, an AI accelerator for data center and enterprise applications, and Bertha-Edge, designed for on-device AI. HyperAccel is also expanding its technology into edge computing and physical AI applications.
The company received the IEEE Micro Best Paper Award in 2025 and was named to the Forbes Asia 100 To Watch 2026 list, among other industry recognitions. Headquartered in Seoul, South Korea, with a presence in Silicon Valley, HyperAccel is pursuing expansion in global AI semiconductor markets. Learn more at www.hyperaccel.ai.
** This press release is distributed by PR Newswire through automated distribution system, for which the client assumes full responsibility. **
HyperAccel to Showcase LPU-Based AI Inference System at SC26, Highlighting Power and Cost Efficiency